
How Salesforce Finds Your Data
यह कंटेंट अभी तक आपकी भाषा में उपलब्ध नहीं है।
Also in 19 languages
Español · 日本語 · Português (Brasil) · Français · Deutsch · Italiano · 한국어 · 简体中文 · Português (Portugal) · 繁體中文 · Bahasa Indonesia · Türkçe · Polski · Tiếng Việt · ไทย · Українська · Español (México) · Français (Canada) · Deutsch (Schweiz)
Module 2 of 5 in the chapter Query and Retrieval Architecture, chapter 8 of the Data Architect course. Each module stands on its own. Previous: Inside the Salesforce Engine · Next: When Salesforce Uses an Index
The question this module answers: What is an index, and which ones does Salesforce give you?
In the last module we opened the engine and found a problem: your records live in shared slots where a normal database index doesn’t fit, so Salesforce copies indexed values into separate tables built for finding them. Now let’s see why that matters. And for this, I like analogies.
Visiting a Library
Section titled “Visiting a Library”Think about a library. A big one: a building full of rooms, and the rooms full of shelves, aisle after aisle. What’s inside? Books. Lots of books.
You walk in looking for a book. You don’t know the whole title. You know it starts with the word “Plumbing.” The books are on the shelves in the library’s own order, not in order by title. So how do you find it?
You start at the first aisle. Pick up the first book, read the title, put it back. Next book. Next book. To be sure you’ve found every book whose title starts with “Plumbing,” you have to touch every book in the library.
What do we call it when we have to touch every record to find the ones we want? A table scan. A full table scan. Is it fast or slow?
It depends on the number of books. With 10 books, a table scan is fast. With 10,000, still fine. In my experience, it’s past a million that you start to feel it, and at 50 million a query that scans can take several seconds. Nothing about the question changed. The librarian didn’t get slower. The number of books changed. That’s why volume matters: the more books in the library, the longer the table scan takes.
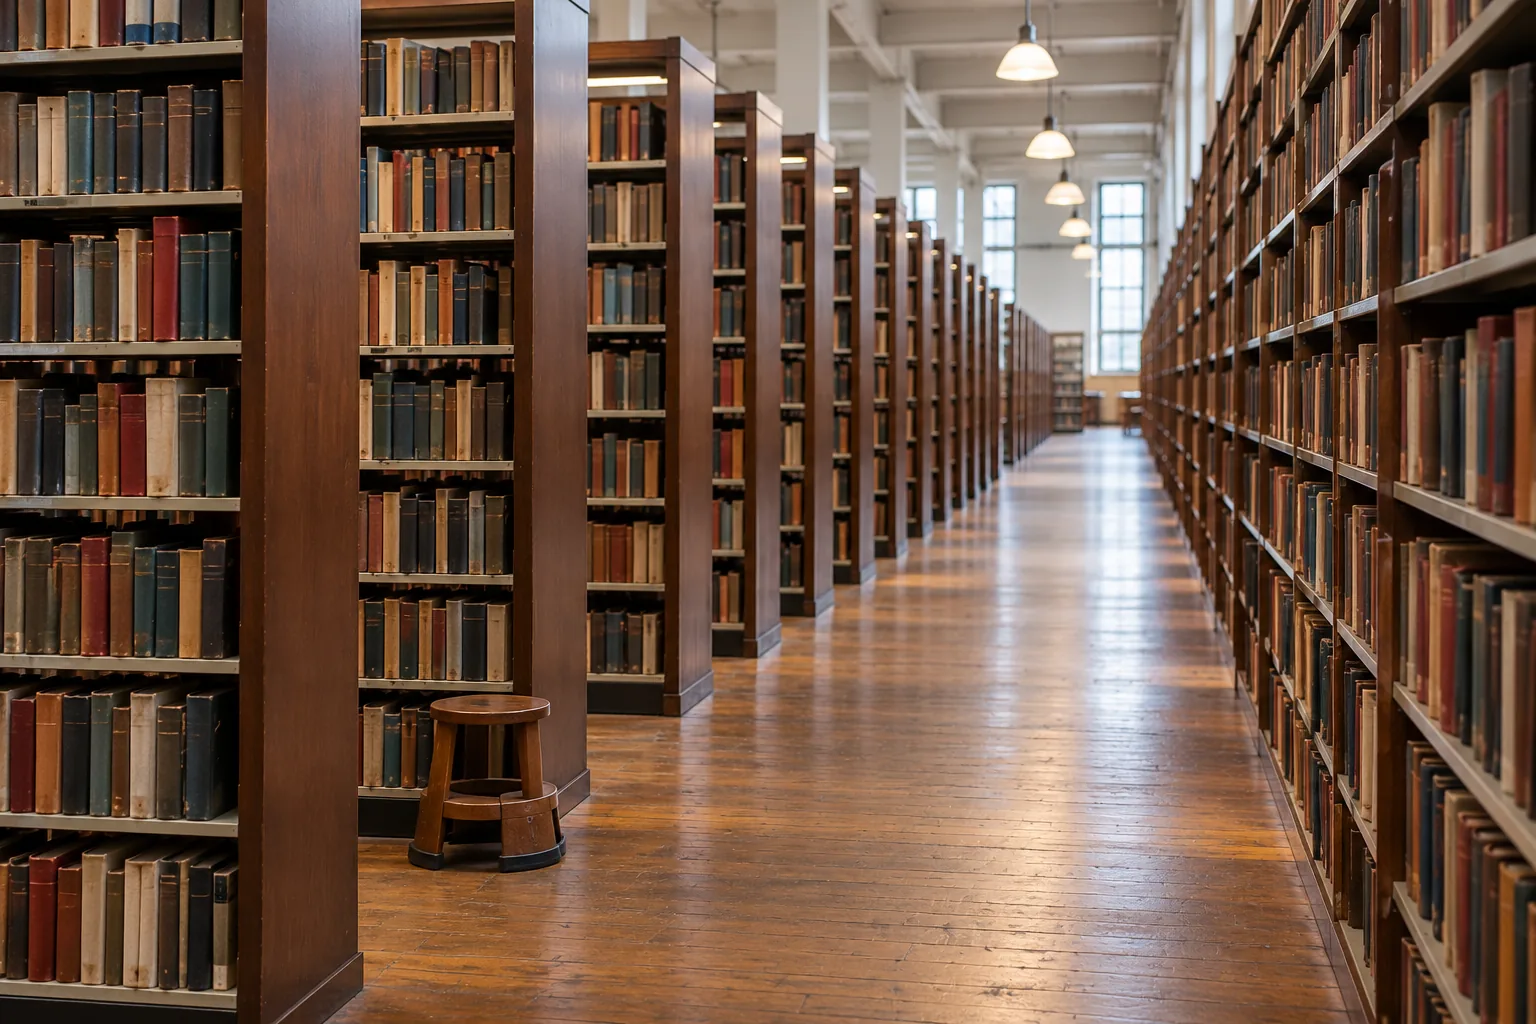
Image generated with AI.
The Advanced Technology: Card Catalogs
Section titled “The Advanced Technology: Card Catalogs”So how did libraries solve this? A long time ago they invented some very advanced technology. (I’m being funny.) Card catalogs. Big cabinets of small drawers, full of small cards. Each card has a little information about one book, the title for example, and the location of the book on the shelves.
Somebody always says: why not just put the books in order by title? Fine. Now I want every book about home repairs. You can’t put the same books in order by title and by subject. But you can do it with cards. Copy the cards and file one set by title, a second set by subject, a third by author. The books stay where they are.
So what do the cards represent? An index. A small copy of a few facts about each book, kept in order by one field, so you can go straight to the right drawer instead of walking the aisles. (Databases keep that order in special sorted structures. You don’t need the details.) You find the card, read the location, and then you go and get the book.
Three ideas are in those drawers, and they’re the three I want you to take into Salesforce:
- An index is a copy. The card isn’t the book; it’s a small copy of a few facts. Salesforce says the same about its own indexes: the platform “creates an index table that contains a copy of the data” (Best Practices for Deployments with Large Data Volumes (opens in a new tab), Winter ‘27).
- There can be more than one index. One set of cards by title, one by subject, one by author. Each answers a different question quickly. In Salesforce, each indexed field is its own way in.
- The card tells you where the book is. In Salesforce, the index entry points to the record, and the platform goes straight to it. Salesforce’s database engineers describe exactly that: “The index entry consists of the index key fields followed by the primary key fields of the corresponding base table record” (A Multi-tenant Relational OLTP Database at Salesforce (opens in a new tab), CIDR 2026). A copy of one field, then the location of the book.
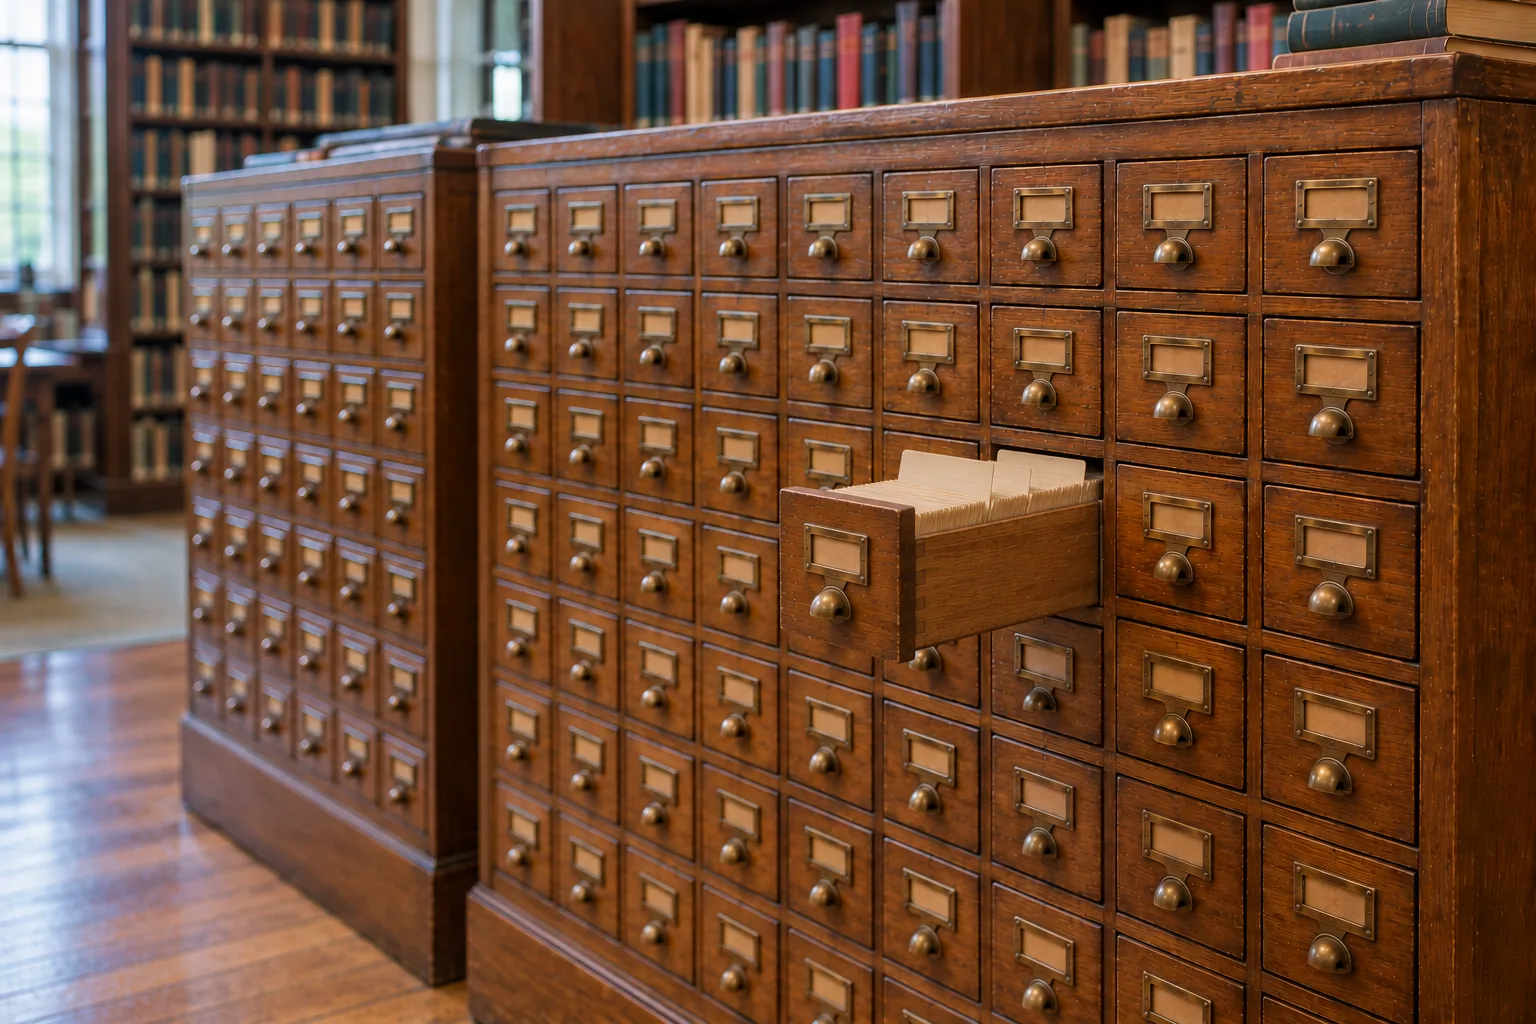
Image generated with AI.
Finding a Book
Section titled “Finding a Book”So what happens when you use the catalog? Say you’re looking for the book titled Plumbing Basics. There are three steps:
- Find the card. Go to the drawer of cards by title and pull the card for Plumbing Basics.
- Read the location. The card tells you where the book is: the aisle, the shelf, the place on the shelf.
- Get the book. Walk straight to that place and take it off the shelf.
You touched one card and one book, not every book in the library. That’s what an index can do for a query. Salesforce finds the entry in the index, reads which record it points to, and goes straight to that record. Using the index can speed up the retrieval enormously, and the bigger the library, the bigger the difference. Notice the word “can”: whether Salesforce actually uses the catalog is a decision we’ll come to in the next module.
Find the card, read the location, get the book.
Every Copy Has to Be Kept Up to Date
Section titled “Every Copy Has to Be Kept Up to Date”Now follow the card catalog one step further. A new book arrives. The librarian puts it on the shelf, and that’s not the end of the job. Somebody has to write a title card, a subject card and an author card, and file each one in the right drawer. A book changes? Find every card that holds what changed and rewrite it: give the book a new title and a new subject, and that’s two cards to pull, rewrite and refile, on top of changing the book itself. Updates aren’t free either. The more sets of cards the library keeps, the more work every new book takes.
That’s the trade I want you to carry through this whole chapter: read performance versus write performance. Each index makes finding records faster, because it’s a small, ordered copy. Each index makes saving records slower, because every insert, and every update to an indexed field, has to update that copy too, and Salesforce does it right then, in the same transaction: the platform keeps its index “by synchronously copying field data marked for indexing” into a separate index table (Platform Multitenant Architecture (opens in a new tab)). Ten indexes on an object means ten copies to check on every save. More indexes, faster reads, slower writes.
And remember the size of the library. With a few hundred books, walking the aisles is quick and the card catalog is extra work for little gain. With 10 million books, the table scan is the problem and the index is the answer. Small libraries can live with table scans; big ones need indexes.
So I don’t look at every field and say “why don’t we index them all?” Suppose Steve Trucking indexed the delivery number, Retail Partner, Recipient, status, scheduled date, postal code, truck, crew and route. Each might help some search; each is another set of cards to keep up to date on every save. The architect’s question isn’t can this field be indexed? It’s does indexing it support an important, repeatable way of finding records strongly enough to justify the cost on every write? Indexes aren’t magic. They’re architecture.
Adding a book: a card in every drawer.
Updating a book: every indexed fact that changes is another write. Faster reads, slower writes.
People sometimes tell me architects don’t need to know this, because Salesforce handles it. Salesforce does handle it. I still want you to understand it, because then several behaviors make sense. Why does an index have a write cost? Another copy has to be updated on every save. Why does the distribution of values matter? An index that points at almost the whole table isn’t a shortcut. Why might Salesforce not use an index that exists? Because sometimes walking the shelves really is cheaper than using the catalog.
Two Ways to Ask
Section titled “Two Ways to Ask”There are two ways to ask Salesforce for records. SOQL, the Salesforce Object Query Language, starts with the word SELECT: you name the object, the fields and the conditions, much like SQL. SOSL, the Salesforce Object Search Language, starts with FIND: you search for text across many objects at once. Most of us write SELECT nearly all the time, but SOSL is working every time someone uses global search. And the two questions go to two different engines. SELECT goes to the database, through the indexes we’ve just met. FIND goes to Salesforce’s search engine: “The Salesforce search architecture is based on its own data store, which is optimized for searching for that text” (Search Architecture (opens in a new tab), Winter ‘27). This chapter is mostly about SELECT; module 5 is about FIND.
Two questions, two languages, two engines.
Standard Indexes
Section titled “Standard Indexes”Back to SELECT and the card catalog. The library has drawers. Which drawers does Salesforce already keep for you? Out of the box, without anyone asking, the platform indexes a short list of fields on most objects. In Salesforce’s own list: RecordTypeId, Division, CreatedDate, Systemmodstamp (LastModifiedDate), Name, Email (for contacts and leads), foreign key relationships (lookups and master-detail), and “the unique Salesforce record ID, which is the primary key for each object” (Indexes (opens in a new tab), Winter ‘27). Those are your standard indexes. Filter on one of them and there’s a drawer waiting.
That list says “most objects”, so what does it look like on a real object? Salesforce doesn’t publish a table per object, so we made our own. Every field in Salesforce carries a flag, IsIndexed: “If true, the field is indexed in the database” (FieldDefinition (opens in a new tab), Tooling API, Winter ‘27). We read that flag in a Developer Edition org on 2026-10-21 (API version 68.0). Your org can differ, because some indexed fields only exist once a feature is turned on: RecordTypeId once the object has record types, Division once divisions are enabled.
Standard indexes on standard objects (indexed out of the box, before anyone asks):
| Object | Indexed out of the box |
|---|---|
| Account | Id, Name, OwnerId, ParentId, CreatedDate, SystemModstamp, OperatingHoursId |
| Contact | Id, Name, Email, AccountId, ReportsToId, OwnerId, IndividualId, CreatedDate, SystemModstamp |
| Lead | Id, Name, Company, Email, OwnerId, ConvertedAccountId, ConvertedContactId, ConvertedOpportunityId, IndividualId, CreatedDate, SystemModstamp |
| Opportunity | Id, Name, AccountId, ContactId, CloseDate, CampaignId, Pricebook2Id, ContractId, PrimaryPartnerAccountId, OwnerId, CreatedDate, SystemModstamp |
| Case | Id, CaseNumber, Status, IsClosed, ClosedDate, AccountId, ContactId, AssetId, ProductId, EntitlementId, ServiceContractId, ParentId, OwnerId, CreatedDate, SystemModstamp |
| Task | Id, WhoId, WhatId, AccountId, ActivityDate, Status, OwnerId, CreatedDate, CreatedById, SystemModstamp |
(A few more lookups to older or optional features are also indexed: the Data.com and D&B company IDs on Account, Contact and Lead, RuleFilterId on Case and RecurrenceActivityId on Task.)
Standard indexes on custom objects. Every custom object gets the same standard fields (Custom Object Standard Fields (opens in a new tab)), and these are indexed from the day you create it:
| On every custom object | Indexed out of the box? |
|---|---|
| Id (the record ID) | Yes |
| Name | Yes |
| OwnerId (objects with an owner; on a detail object the master decides) | Yes |
| CreatedDate | Yes |
| SystemModstamp | Yes |
| IsDeleted (in the Recycle Bin or not) | Yes |
| RecordTypeId | Yes, once the object has record types |
| Every lookup and master-detail field you add | Yes |
| CreatedById, LastModifiedById | No |
| LastModifiedDate | No: SystemModstamp is the indexed one |
| Any other custom field | No, until you ask (next section) |
Look at those tables for a minute, because they tell you a lot. Name is there, so finding a record by its name has a path. Every lookup is there, so finding the child records of one parent (the work orders for one account, the line items for one work order) has a path. CreatedDate and SystemModstamp are there, so “what’s new” and “what changed since yesterday” have a path. And look at Case: Status, IsClosed and ClosedDate are indexed. Hold on to that; it matters in the next module. If one of your important ways of finding records is already in these tables, you start with an advantage. To see your own org, open the object in Object Manager and look at Fields & Relationships, where each field shows whether it’s indexed.
Test knowledge. Know Salesforce’s standard indexed fields: RecordTypeId, Division, CreatedDate, Systemmodstamp (LastModifiedDate), Name, Email on contacts and leads, lookup and master-detail fields, and the record ID.
Custom Indexes
Section titled “Custom Indexes”What if the field you search on isn’t on the list? Anybody know how to create a custom index in Salesforce? Two ways, in Salesforce’s words: “You can create custom indexes by contacting Salesforce Customer Support or by deploying a custom index XML file via the Metadata API” (same source). The ones Support creates in production “are copied to all sandboxes that you create from that production environment”. Even the Metadata API route starts with a conversation: the CustomIndex type says to review Salesforce’s guidance on indexes “and then contact Salesforce Customer Support” (CustomIndex (opens in a new tab), Metadata API Developer Guide, Winter ‘27).
And there’s a quieter way, one I always ask about in class. Mark the field as an External ID. “External IDs cause an index to be created on that field. The query optimizer then considers those fields” (same source). Only some field types can be External IDs: Auto Number, Email, Number and Text. The same goes for marking a custom field Unique: Salesforce lists “Custom fields that are marked as External ID or Unique” among the fields indexed by default (Working with Very Large SOQL Queries (opens in a new tab), Apex Developer Guide, Winter ‘27). Steve Trucking already did this without thinking about it. Each Retail Partner sends its own delivery reference, say DLV-8472914, and we made that field an External ID so integrations could match on it. That field got a drawer of its own.
Salesforce also does some of this for you now. The same page says: “Fields not indexed by default are automatically indexed when the Salesforce optimizer recognizes that an index can improve performance for frequently run queries.” So an org can have indexes that nobody asked for. Don’t design on the hope that it happens, though: Salesforce doesn’t say which queries qualify or when, so check the field in Object Manager instead of assuming.
So should we index everything? Remember how every copy has to be kept up to date: every drawer is another card to write on every save. In class I tell people that every custom index request is a conversation, and you should come with a good argument: the query, the volume, how the values are spread, and why. That’s not Salesforce being difficult. You don’t want unlimited indexes either. You could speed up your queries and slow down every insert and update.
Test knowledge. A custom index comes from Salesforce Customer Support or the Metadata API, and marking a custom field as an External ID (Auto Number, Email, Number or Text) or Unique indexes it.
Which Fields Can Be Indexed
Section titled “Which Fields Can Be Indexed”So you’ve found the field your important query filters on, and it isn’t in the standard tables. Can it have a drawer? Usually yes. Salesforce “supports custom indexes on custom fields, except for text areas (long), text areas (rich), non-deterministic formula fields, and encrypted text fields” (Indexes (opens in a new tab), Winter ‘27). The same page lists more fields the platform can’t index: multi-select picklists, currency fields in an org with more than one currency, long text areas, and binary fields (a blob, a file or encrypted text).
| Field | Can it be indexed? |
|---|---|
| Text, Number, Email, Auto Number | Yes. Mark it as an External ID and you get the index without a request |
| Date, Date/Time, Checkbox, Picklist, Phone, and most other custom fields | Yes, as a custom index: ask Salesforce Customer Support or deploy it with the Metadata API |
| Lookup and master-detail | Already indexed: they’re standard indexes |
| Standard fields not in the standard tables | Ask Salesforce Customer Support |
| Formula | Only if it’s deterministic (next) |
| Text Area (Long), Text Area (Rich) | No |
| Multi-select picklist | No |
| Currency, in an org with more than one currency | No |
| Encrypted text (the older Classic encryption field) | No |
| A field encrypted with Shield Platform Encryption | Only with deterministic encryption, which “supports single-column indexes and single and double-column unique indexes” (Filter Encrypted Data with Deterministic Encryption (opens in a new tab)) |
Why can’t a long text area have a card? Think about the card catalog. A card holds a small copy of one fact. A long text area can hold a whole letter. A multi-select picklist holds several values in one field. Neither one is a single, short value you can put in order in a drawer.
Can You Index a Formula Field?
Section titled “Can You Index a Formula Field?”Yes, under certain conditions. “Custom indexes can be created on deterministic formula fields” (same source). Deterministic means the formula always gives the same answer for the same record until somebody saves that record. Then the platform can do what it does for every index: write the card when the record is saved.
A non-deterministic formula can change its answer without the record being saved, so nobody would ever update its card. Salesforce’s reason: “Because some values vary over time or change when a transaction updates a related entity, the platform can’t index non-deterministic formulas” (same source). There are two kinds of reason to remember:
- The value changes over time. The formula uses TODAY() or NOW(). “Days since this delivery was scheduled” is a different number tomorrow, and nothing on the record changed.
- The value lives on another object. The formula reaches through a lookup or master-detail, like
Account.Region__con a work order, or uses another formula that does. When someone edits the account, every work order’s answer changes, and none of those work orders were saved.
The same page names a few more: formulas that use the owner, auto number, division or audit fields (CreatedDate and CreatedById are the exceptions), formulas that refer to a field that can’t be indexed itself, and formulas that use certain standard fields with special behavior, such as Opportunity Amount and IsClosed, or Case IsClosed and ClosedDate. And if you change a formula after it’s indexed, the index is rebuilt.
So what do you do when the formula you wanted reaches into another object? Salesforce points to a way around it: filter through the relationship in the query itself. “As long as the referenced field is indexed, the cross-object notation can have multiple levels” (same source). Instead of WHERE Account_Region__c = 'West' on a formula, write WHERE Account.Region__c = 'West' and index Region__c on the account.
Test knowledge. Know which fields can’t have a custom index: long and rich text areas, multi-select picklists, encrypted text, currency in a multi-currency org, and non-deterministic formulas. A formula can be indexed only if it’s deterministic: no TODAY() or NOW(), and no values from another object through a lookup.
Index Tables
Section titled “Index Tables”One more piece, and it connects back to the engine. In module 1 we saw that your custom field values live in shared flex columns, where one column can hold a truck number for one company and an ice cream flavor for another. A normal database index can’t be built on that. So what does Salesforce do? It makes a copy. “The Salesforce multitenant architecture makes the underlying data table for custom fields unsuitable for indexing. To overcome this limitation, the platform creates an index table that contains a copy of the data, along with information about the data types. The platform builds a standard database index on this index table” (same source). The card catalog is a real thing, kept in its own table, and every save keeps it in step.
From module 1: indexed values are copied into a separate, typed table built for finding.
One detail from that same page matters later: “By default, the index tables don’t include records that are null (records with empty values).” A record with an empty field has no card in that drawer. You can ask Salesforce Customer Support for custom indexes that include null rows, and existing ones then have to be enabled and rebuilt (same source). So if “find the records where this field is empty” is an important question, plan for it. Module 3 comes back to it.
What an Architect Decides Here
Section titled “What an Architect Decides Here”- Which important ways of finding records the standard indexes already cover.
- Which fields justify a custom index (or an External ID), given the extra write on every save.
- Whether a field’s type allows an index at all, decided when the field is designed, not when the query is slow.
- Whether finding empty values matters, since index tables leave out null rows by default.
- Which questions are SELECT questions for the database and which are FIND questions for search.
A table scan touches every book. An index is the card catalog: a small copy, one set per index, each card pointing to the book, and each one updated on every save. Salesforce keeps some drawers for you (standard indexes), builds others when you ask (custom indexes), and keeps them all in index tables, copies built for finding. So now we have drawers. Does that mean every question is fast? No. In the next module we’ll see the three things that have to be true before Salesforce uses one.
Explore
Section titled “Explore”- Salesforce Developers, Best Practices for Deployments with Large Data Volumes (Winter ‘27): Indexes (opens in a new tab), checked 2026-11-01: the standard indexed fields, custom indexes and External IDs, which fields can’t be indexed, index tables as a copy of the data, and null rows.
- Salesforce Architects, Platform Multitenant Architecture (opens in a new tab), checked 2026-11-01: indexed values copied synchronously into MT_Indexes.
- Salesforce Developers, Tooling API (Winter ‘27), FieldDefinition (opens in a new tab), checked 2026-11-01: the IsIndexed flag on every field.
- Salesforce Developers, Apex Developer Guide (Winter ‘27), Working with Very Large SOQL Queries (opens in a new tab), checked 2026-11-01: External ID and Unique fields are indexed by default; the optimizer can index other fields automatically.
- Salesforce Developers, Metadata API Developer Guide (Winter ‘27), CustomIndex (opens in a new tab), checked 2026-11-01: deploying a custom index still starts with Salesforce Customer Support.
- Salesforce Help, Filter Encrypted Data with Deterministic Encryption (opens in a new tab), checked 2026-11-01: deterministic encryption supports single-column indexes.
- Salesforce Help, Custom Object Standard Fields (opens in a new tab), checked 2026-11-01: the standard fields every custom object has.
- Salesforce Developers, Best Practices for Deployments with Large Data Volumes (Winter ‘27), Search Architecture (opens in a new tab), checked 2026-11-01: search has its own data store.
- Arora and others (Salesforce), A Multi-tenant Relational OLTP Database at Salesforce (opens in a new tab), CIDR 2026, checked 2026-11-01: an index entry is the index key followed by the record’s primary key.
- In this course: Inside the Salesforce Engine, the module before this one.