
소유권, 부모, 조회 스큐
19개 언어로도 제공
English · Español · 日本語 · Português (Brasil) · Français · Deutsch · Italiano · 简体中文 · Português (Portugal) · 繁體中文 · Bahasa Indonesia · Türkçe · Polski · Tiếng Việt · ไทย · Українська · Español (México) · Français (Canada) · Deutsch (Schweiz)
Data Architect 과정 7장인 규모를 위한 설계의 모듈 2/4. 각 모듈은 독립적으로 읽을 수 있습니다. 이전: 볼륨이 모든 것을 바꿀 때 · 다음: 볼륨이 공유 모델을 만날 때
이 모듈이 답하는 질문: 너무 많은 레코드가 한 대상을 가리키면 어떻게 될까요?
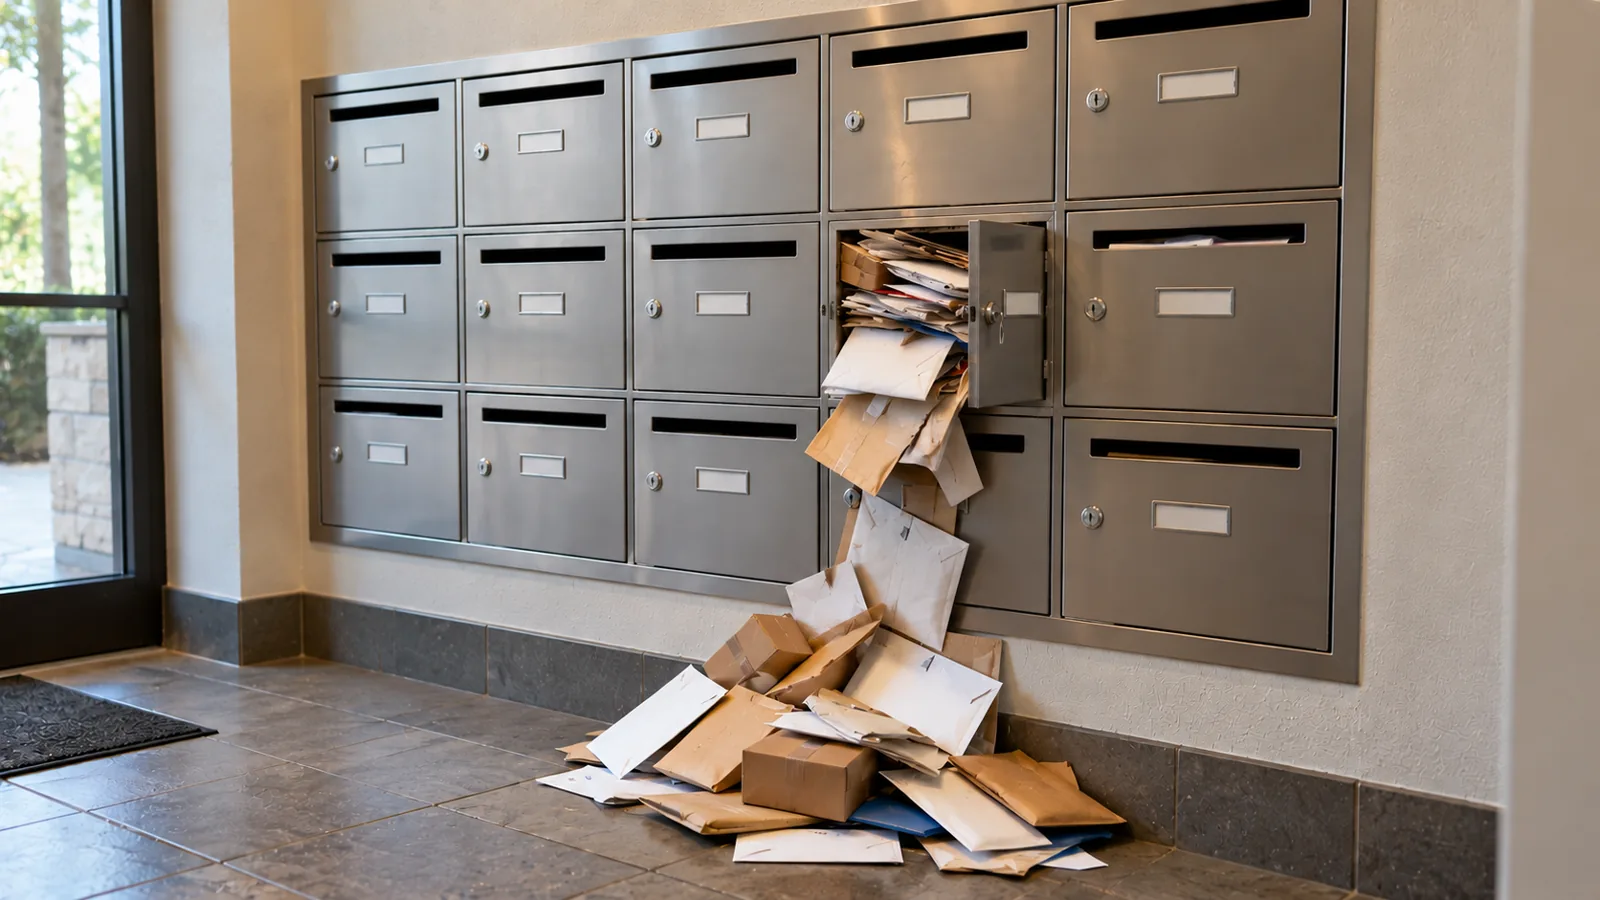
대용량 데이터 문제가 늘 레코드가 너무 많아서 생기는 것은 아닙니다. 때로는 너무 많은 레코드가 같은 대상에 연결되어서 생깁니다. 소유자 하나, 계정 하나, 부모 하나, 조회 값 하나. 교통을 생각해 보십시오. 도시는 자동차가 수백만 대여도 굴러갑니다. 문제는 모두가 오후 5시에 같은 고속도로 출구로 나갈 때 시작됩니다. 총량도 중요하고, 쏠림도 중요합니다. 저는 이런 쏠림을 핫스팟이라고 부르고, Salesforce는 데이터 스큐(data skew)라고 부릅니다. 여러 종류가 있지만 밑에 깔린 생각은 하나입니다. 모델의 한 지점으로 너무 많은 활동이 모이는 것.
상위-하위 스큐
섹션 제목: “상위-하위 스큐 ”The easiest to picture. One account with 100 contacts: nothing unusual. A thousand: probably fine. Ten thousand: now I’m paying attention. My design rule is no more than about 10,000 children under one parent, and Salesforce’s guidance draws the same line: “a large number of child records (10,000 or more) with a single parent account” is a common cause of poor performance (Parent-Child Data Skew (새 탭에서 열림)). Salesforce’s own example shows why. Put 300,000 contacts under one account. A user who can see one of those contacts gets implicit access to the account. When that user loses access to the contact, Salesforce has to check the other 299,999 contacts before it can decide whether to remove the user’s access to the account. Do that for many users at once, and it gets expensive. Salesforce also names one way to take part of that cost away: where your security requirements allow, set the child object to Controlled by Parent, so there are no parent implicit shares to maintain (same source). In practice, it’s the most common skew I see, and I’ve seen users notice visible lag at around 20,000 children under one parent. Where somebody feels it depends on what the system is doing. That’s why 10,000 is a design threshold, not a promise that record 10,001 breaks anything. The real question is: why are all these records pointing at the same parent? ⟲
Step 1 of 2: every line points at one account. That’s the hot spot. ⟲
“미할당” 계정, 그리고 계정 풀
섹션 제목: ““미할당” 계정, 그리고 계정 풀 ”The classic case is contacts with no real account. Somebody decides every contact needs an account, so they create Unassigned Contacts and put every contact without an account there. Problem solved, until there are 300,000 contacts under it. We created an artificial hot spot because the model required us to put everything somewhere, and the relationship doesn’t even carry business meaning. It worked beautifully at 500 records. Then the Number of Zeros caught up with it. ⟲
What do you do when you’ve got a million contacts under it? I’ve seen child accounts by state, one unhandled-contacts account per state. I’ve seen an automatic version: whenever an account reaches 10,000, create another one. It can be a little awkward, but it spreads the load. ⟲
One answer is an account pool: Unassigned Contacts 001, 002, 003 and so on, with the children spread across them, each kept under the threshold. It works, and it’s Salesforce’s own advice: “Distribute child records so that no parent has more than 10,000 child records,” and for contacts without real accounts, “set up several dummy accounts and distribute the contacts among them” (Best Practices for Deployments with Large Data Volumes: General (새 탭에서 열림), Winter ‘27). But those aren’t real accounts; they’re architecture artifacts. Users will ask who “Unassigned Contacts 017” is and why it’s in their search results. So when I use a pool, I hide the placeholder parents from normal business experiences as much as I can. It’s a recurring trade-off: sometimes scale forces a structure that exists for the platform, not the business. When it does, don’t pretend it’s business data. Name it, document it, hide it where appropriate. ⟲
Step 2 of 2: the same contacts, spread across a pool. Nothing moved but where they point. ⟲
Master-Detail at Volume
섹션 제목: “Master-Detail at Volume”Contacts under an account are a lookup. Master-detail is a different decision, and it’s one you make in the data model, long before the records arrive. Here’s the question I ask in class: would an invoice ever have more than 10,000 line items? No, it never would. So an invoice and its lines can be master-detail all day long. Now ask the same question of every master-detail relationship you’re about to build: at the volume we expect, will one parent ever pass 10,000 children? ⟲
Salesforce draws the same line: “As a best practice, don’t exceed 10,000 child records for a master-detail relationship” (개체 관계에 대한 고려 사항 (새 탭에서 열림)). Master-detail is the strongest relationship Salesforce gives you, and that’s exactly why the number matters. The detail record has no owner of its own; its access is controlled by the parent. Delete the parent, and every child goes with it. A child can’t move to another parent unless you allowed reparenting. Roll-up summaries on the parent have to keep up as the children change. And saving a child can lock the parent, which is why Salesforce’s loading advice is to group child records by their parent “to minimize locking conflicts” (Loading Data from the API (새 탭에서 열림)). With ten children, none of that is noticeable. With a hundred thousand, every one of them is. ⟲
It’s also hard to undo. A master-detail relationship can only be converted to a lookup when the parent has no roll-up summary fields, and converting it changes the child’s sharing to Public Read/Write (same source). By the time volume tells you it was the wrong choice, the relationship may be holding up reports, sharing and automation. Count the children before you choose the relationship. ⟲
Steve Trucking has one of these decisions in its model. Each Retail Partner sends a Manifest (Manifest__c, a custom object) for each distribution center, for each working day. Manifest is custom, so master-detail to the partner’s account is allowed, and it’s tempting: the manifest would inherit the partner’s sharing, which is exactly the isolation we want. Now count. Our largest partner has nine or more DCs: nine manifests a working day, about 2,700 a year. Past 10,000 in under four years, under one parent, and every manifest revised on the day, so every revision would touch the partner’s account. That’s why the model makes Manifest a lookup and handles partner access through sharing. The invoice stays small; the manifests keep coming. ⟲
Step 1 of 2: master-detail, where the parent stays small. ⟲
Step 2 of 2: a lookup, where the children keep coming. ⟲
Watch Account with its contacts and opportunities too. It isn’t master-detail, but it behaves like a pseudo master-detail, with implicit sharing to the parent, which is why the 10,000 guidance shows up there as well. None of this means never use master-detail at scale. It means don’t choose a strongly coupled relationship and then act surprised that the records are strongly coupled. ⟲
Test knowledge. Know the 10,000-children guidance for master-detail, and what master-detail brings with it at volume: no owner on the detail (access controlled by the parent), cascade delete, no reparenting unless allowed, roll-up summaries, and parent locking when children are saved. Converting to a lookup needs no roll-up summaries on the master. ⟲
소유권 스큐
섹션 제목: “소유권 스큐 ”Now the owner. I ask the room: who owns a million records? The admin? Is the admin sitting there creating a million records? Usually it’s the integration user or the data load user. The records come in, and nobody knows who to give them to. We create an integration user, it creates records, nobody thinks about ownership (“it’s just the integration user”), and a year later that user owns 2 million records. Salesforce calls it ownership data skew when one user owns more than 10,000 records of an object, and the classic example is all the unassigned leads parked on a dummy user (Ownership Data Skew (새 탭에서 열림)). That doesn’t mean a user can never own more. It means understanding the consequences: ownership isn’t a Created By stamp. It drives the role hierarchy, sharing rules and recalculation: behind the scenes, Salesforce keeps share records for the owner’s records above them in the role hierarchy. Attach millions of records to one owner who sits deep in the sharing model, and changing anything about that owner gets expensive. ⟲
The guidance matches what I teach in class. If a few users must own a very large number of records, give them no role; if they need one, put them in a separate role at the top of the hierarchy and don’t move them, and keep them out of public groups used as sources for sharing rules (same source). One catch with the top role: that user inherits access to all the data owned by or shared with the users below them. You could spread the records across a bunch of users instead, but for an integration user or a data load user, that typically isn’t worth the trouble. ⟲
We’re isolating the hot spot from the structures that trigger recalculation. Imagine a user who owns 5 million records being moved in a reorganization. That isn’t moving a box on the org chart; Salesforce may have to re-evaluate access across 5 million records. At this scale, organizational changes become data operations. ⟲
Test knowledge. Know the skew thresholds and the fixes: ownership skew when one user owns more than 10,000 records of an object (no role, or a separate role at the top that doesn’t move, and out of public groups used by sharing rules); parent-child skew at about 10,000 children under one parent. ⟲
기계가 만든 레코드는 누가 소유해야 할까요?
섹션 제목: “기계가 만든 레코드는 누가 소유해야 할까요? ”누가 레코드를 만들었는지와 누가 소유하는지는 같은 질문이 아닙니다. Redrock이 API로 배송 50만 건을 보내고, 통합 사용자가 그것을 만듭니다. 그 사용자가 영원히 소유해야 할까요? 그럴 수도 있지만, 만들었다는 이유만으로는 아닙니다. 그리고 이제는 에이전트도 레코드를 만듭니다.
제 입장은 이렇습니다. 소유권이 공유에 중요한지에 달려 있습니다. 통합 사용자나 에이전트 사용자는 유효한 사용자이고 레코드를 소유할 수 있습니다. 그 객체에서 소유권이 (역할 계층이나 공유 규칙을 통해) 접근을 좌우한다면, 비즈니스가 요구하는 소유자에게 레코드를 할당하십시오. 실제 사용자, 객체가 지원한다면 큐, 또는 전용 소유자 사용자입니다. 소유권이 접근을 좌우하지 않는다면, 에이전트나 통합 사용자를 소유자로 두는 편이 더 나을 수 있습니다. 감사 추적이 레코드를 만든 주체로 곧장 이어지기 때문입니다. 어느 쪽이든, 보통 사람이 레코드를 소유한다는 이유로 기계가 만든 레코드를 기계적으로 재할당하지 말고, 이 객체에서 소유자가 무엇을 뜻하는지 정하십시오. 그리고 “작성자”는 여전히 남아 있다는 것을 기억하십시오. 소유권을 재할당해도 통합이 만들었다는 사실은 사라지지 않습니다. 작성자와 소유자는 다른 질문에 답합니다. 필드 하나가 둘 다에 답하게 만들면 나쁜 모델이 됩니다.
조회 스큐
섹션 제목: “조회 스큐 ”A lookup can be a hot spot too: millions of records pointing at the same location, category, reference record or configuration record. Salesforce’s own training defines it: “Lookup skew happens when a very large number of records are associated with a single record in the lookup object” (Large Data Volumes: Design Your Data Model (새 탭에서 열림)). The danger isn’t “lots of lookups.” It’s concentration combined with activity: if millions of active records reference one record, and transactions keep touching that relationship, operations start colliding over it. That’s record locking, which chapter 11 covers. For now, recognize the shape: many active records, one heavily referenced record, worth inspecting. ⟲
모든 스큐가 똑같이 위험하지는 않습니다
섹션 제목: “모든 스큐가 똑같이 위험하지는 않습니다 ”“10,000 = 나쁨”을 외우지 마십시오. 절대 바뀌지 않는 참조 값을 가리키는 이력 레코드 5만 개가 공유에서 아무 역할도 없고 동시 활동도 거의 없다면 괜찮을 수 있습니다. 자주 바뀌고, 공유를 좌우하고, 롤업을 공급하고, 여러 통합이 동시에 건드리는 부모 아래의 활성 레코드 2만 개는 전혀 다른 이야기입니다. 볼륨에 모양이 있듯이 스큐에도 모양이 있습니다. 거기에 몇 개의 레코드가 모이나요? 얼마나 자주 바뀌나요? 부모가 바뀌나요? 그 관계가 공유나 잠금을 좌우하나요? 통합이 자식을 동시에 갱신하나요? 소유자나 부모를 옮기면 재계산이 일어나나요? 숫자는 어디를 볼지 알려 주고, 동작은 얼마나 걱정할지 알려 줍니다.
Steve Trucking: 핫스팟은 어디에 있을까요?
섹션 제목: “Steve Trucking: 핫스팟은 어디에 있을까요? ”5년 시점에 우리는 약 작업 주문 900만 건을 예상했습니다. 누군가 “모든 배송을 통합 사용자가 소유하게 하죠”라고 한다고 합시다. 레코드 900만 개, 소유자 한 명. 배송을 공유하는 데 소유권이 중요한가요? 아니라면, 앞에서처럼 역할 계층과 공유 규칙 그룹에서 격리된 전용 대량 소유자가 통할 수 있습니다. 중요하다면, 통합 소유자 한 명은 잘못된 비즈니스 모델입니다. 통합이 레코드를 만든다고 해서, 통합이 그것을 소유해야 한다는 뜻은 아닙니다.
Then the Retail Partner. Every work order carries its partner, deliberately, because partner isolation matters. But if one partner is 40% of the business, five years of deliveries is about 3.6 million work orders under one partner account. Does that make the relationship wrong? No. The business relationship is real, and I’m not going to invent 400 fake Redrock accounts because I don’t like the count. But I am going to look for a split the business would recognize. Each partner has real distribution centers, so a child account per DC under the partner spreads the work orders nine or more ways while every account still means something. Add archiving completed deliveries after the claims window, and the active children per parent stay low. ⟲
이것이 두 가지 해법의 차이입니다. “미할당 연락처”는 이미 인위적이었으니 풀로 나눠도 잃는 의미가 없습니다. Redrock은 실제 파트너입니다. Redrock 001, 002, 003으로 나누면 모델이 오염됩니다. 실제 DC로 나누면 그렇지 않습니다. 규모를 위한 해법도 의미를 지켜야 합니다. 때로는 다른 관계, 공유 전략, 쿼리 패턴, 저장 모델, 아카이브 정책이 답이지, 실제 비즈니스 엔티티에 가짜 정체성을 주는 것은 결코 답이 아닙니다.
Inspect, not bad. Concentration matters, not the total. ⟲
다이어그램에서 핫스팟을 찾으십시오
섹션 제목: “다이어그램에서 핫스팟을 찾으십시오 ”제가 좋아하는 연습이 있습니다. 데이터 모델을 펼치고 객체만이 아니라 화살표를 보십시오. 관계마다 물으십시오. 이 화살표의 이쪽에 레코드가 몇 개나 쌓일 수 있을까? 그리고 소유자에 대해서도 같은 질문을 하십시오. 이제 3년, 5년, 10년을 상상해 보십시오. 레코드는 어디에 몰리나요? 내일의 문제는 흔히 거기에 숨어 있습니다.
시험 너머: AI가 바꾸는 것. 사람은 하루에 레코드를 20개쯤 만들지만, 에이전트는 수천 개를 만들 수 있습니다. 에이전트에게 자기 사용자를 주고 모든 레코드를 그 사용자가 소유하게 두면, 소유권 스큐는 사람일 때보다 훨씬 빨리 나타납니다. 에이전트의 소유권이 잘못된 것은 아니지만, 볼륨이 기본값을 아키텍처의 일부로 만들어 버리기 전에, 에이전트가 만든 레코드에서 소유자가 무엇을 뜻하는지 정하십시오.
아키텍트가 여기서 결정하는 것
섹션 제목: “아키텍트가 여기서 결정하는 것 ”- 상위-하위, 소유권, 조회 관계가 레코드를 어디에 몰리게 하는지, 그리고 그것이 핫스팟이 될 만큼 활발한지.
- 기계가 만든 레코드를 통합 사용자나 에이전트 사용자가 계속 소유할지, 아니면 소유권이 접근을 좌우하기 때문에 재할당할지.
- 대량 레코드 소유자를 역할 계층과 공유 규칙 그룹에서 어떻게 격리할지.
- 인위적인 부모를 언제 풀로 나눌 수 있고, 실제 관계에는 언제 의미 있는 분할이 대신 필요한지.
- Whether each master-detail relationship stays under about 10,000 children per parent at projected volume, or should be a lookup. ⟲
수천 명의 소유자와 부모에 흩어진 레코드 100만 개는 한 곳을 가리키는 레코드 100만 개와 아주 다르게 동작합니다. 핫스팟을 일찍 찾으십시오. 소유자, 부모, 조회 관계, 0의 개수가 모이는 모든 곳. 목표는 모든 큰 관계를 없애는 것이 아닙니다. 어떤 관계는 비즈니스를 올바르게 표현합니다. 고속도로를 개통하기 전에 교통이 어디로 몰릴지 아는 것입니다. 일단 레코드 수백만 개가 같은 출구로 향하기 시작하면, 길을 바꾸기가 훨씬 어려워지기 때문입니다.
더 알아보기
섹션 제목: “더 알아보기 ”- Salesforce Developers, Best Practices for Deployments with Large Data Volumes, Loading Data from the API (새 탭에서 열림) (Winter ‘27): group child records by parent to minimize locking conflicts, checked 2026-11-01. ⟲
- Salesforce Help, 개체 관계에 대한 고려 사항 (새 탭에서 열림): no more than 10,000 child records for a master-detail relationship; converting master-detail to lookup, checked 2026-11-01. ⟲
- Salesforce Developers, Designing Record Access for Enterprise Scale (Winter ‘27): Ownership Data Skew (새 탭에서 열림) and Parent-Child Data Skew (새 탭에서 열림), checked 2026-11-01. ⟲
- Salesforce Developers, Best Practices for Deployments with Large Data Volumes: General (새 탭에서 열림) (Winter ‘27), the 10,000-record owner and parent guidance, checked 2026-11-01. ⟲
- Trailhead, Large Data Volumes: Design Your Data Model (새 탭에서 열림): parent-child, ownership and lookup skew, checked 2026-11-01. ⟲
- Salesforce engineering blog, Managing Lookup Skew to Avoid Record Lock Exceptions (새 탭에서 열림) (2013; older, but still the clearest explanation; checked 2026-11-01). ⟲
- SteveTechArc, Salesforce Documents by Release: these guides, once a year from Winter ‘16, each with an archived copy. ⟲