
The Data Model Is the Bones
Also in 28 languages
Español · 日本語 · Português (Brasil) · Français · Deutsch · Italiano · 한국어 · 简体中文 · Português (Portugal) · 繁體中文 · Bahasa Indonesia · Türkçe · Polski · Tiếng Việt · ไทย · Nederlands · العربية · עברית · Українська · हिन्दी · Русский · Svenska · Dansk · Norsk bokmål · Suomi · Español (México) · Français (Canada) · Deutsch (Schweiz)
Module 2 of 7 in the chapter Thinking Like a Data Architect, the first chapter of the Data Architect course. Each module stands on its own. Previous: Thinking Like an Architect · Next: The Reversibility Test
The question this module answers: Why does the data model matter more than anything built on it, and how do you judge one?
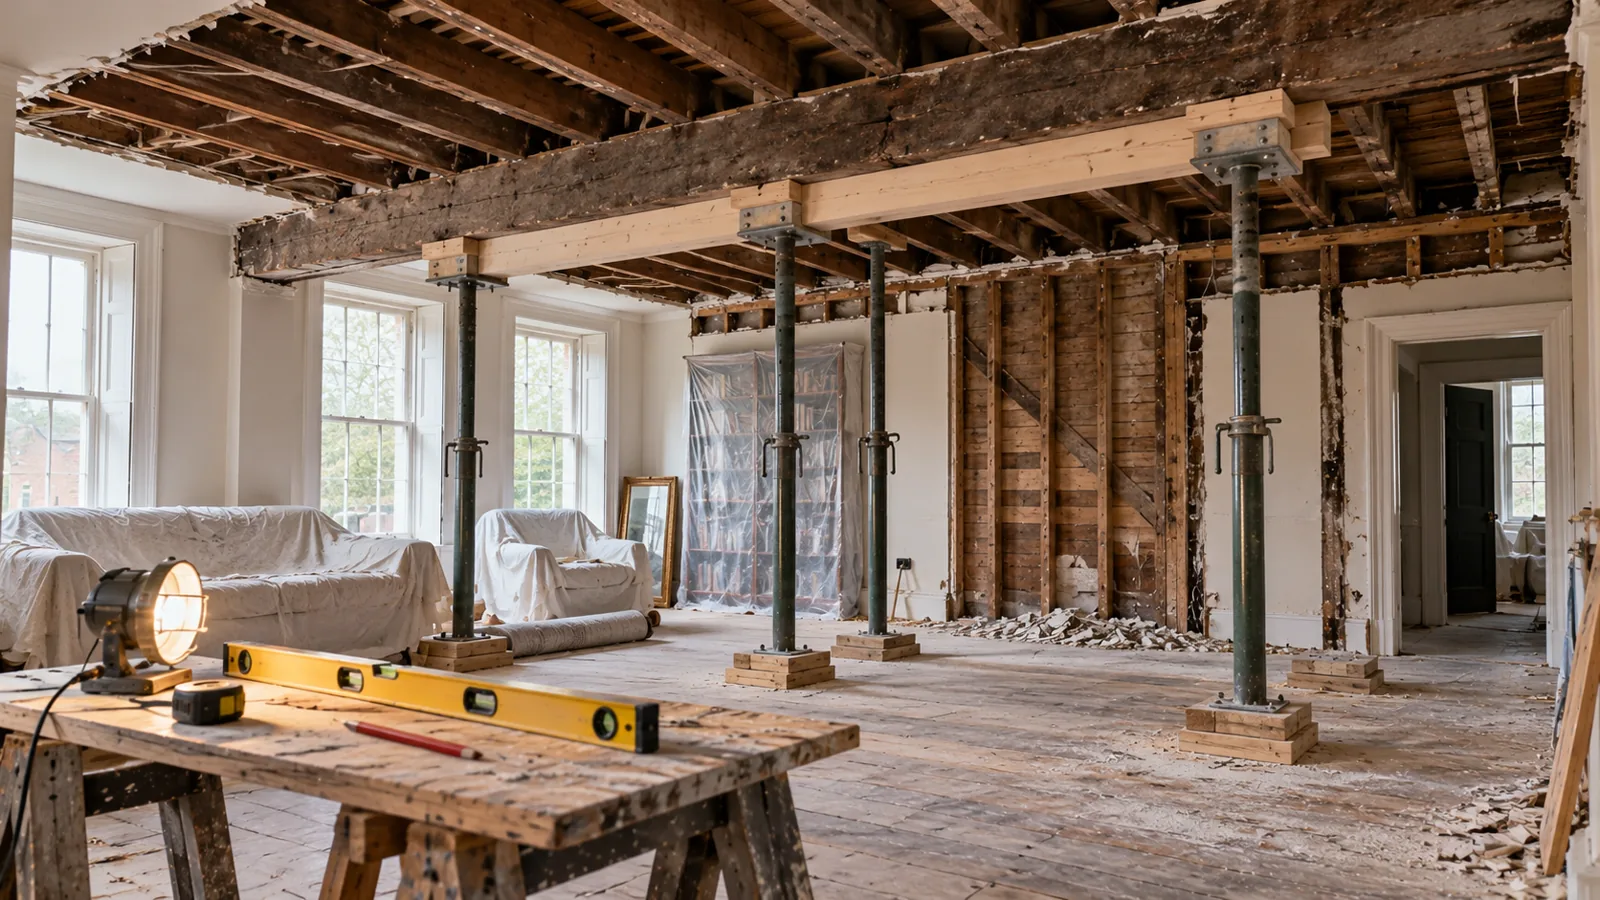
When I teach data architecture, there’s a phrase I come back to again and again: the data model is the bones.
The data model is the bones of the system. Everything else is built around it, and it’s what holds the rest of the body together. You don’t see the bones when you look at someone, but they decide how tall that person stands, how they move, and what they can carry.
Think about everything we build in a Salesforce implementation. We build automation around the data model. We write Apex against it, and Flows that read and update it. We build integrations that send data into it and pull data out of it. We create reports and analytics on it, and we design security around it. And increasingly, we build AI agents that need to understand and act on that data. All of it depends on the structure underneath.
That’s why getting the data model right early matters so much. You can change the bones later. But it’s probably going to hurt.
Start With the Business
Section titled “Start With the Business”A good data model starts with a simple question: what does the business actually need to represent? Not “what Salesforce objects do we have?” And definitely not “what can I build quickly?”
We’re trying to understand the business first. What are the important things in this business? How are they related? Who owns them? How do they change over time? What needs to be remembered, and what is shared across business processes? Only after we understand those things should we start translating them into objects, fields and relationships.
This sounds obvious. In practice, it’s very easy to get backward. Someone recognizes something that looks like an Opportunity, a Case or an Asset and immediately starts designing around it. Sometimes that’s exactly right. Sometimes we’re trying to put a square peg into a round hole, and once enough has been built around that decision, getting the peg back out becomes very expensive.
Here’s a question I hear all the time. A customer’s business can have many delivery locations. Should each location be an Account, or a custom object? Before you answer, notice what you’d need to know first: what a location means to this business, and what happens to it. That’s modeling the business before the objects. (I’ll give you my answer in chapter 3.)
Support. Grow. Perform.
Section titled “Support. Grow. Perform.”When I’m looking at a data model, I want it to pass three tests: support the business, grow with the business, and perform.
Support. The model has to support what the business is actually trying to accomplish. There’s a big difference between a model that can technically store the data and one that actually represents the business well. If I’m constantly adding strange fields, special flags, complicated automation and exceptions because the model doesn’t quite fit, I start asking whether the problem is really the automation. Maybe the model is wrong. A good model should make the business easier to understand, not harder.
Grow. When I say grow, I don’t just mean more records. Volume matters: ten thousand records and a hundred million create very different problems. But businesses also grow in complexity. They add products, enter new markets, acquire companies, change processes, add channels and connect new systems. They discover that something they thought was one thing is actually five different things. A model that works beautifully for today can become a trap if there’s no room for tomorrow. That’s why I prefer designs that grow through addition rather than designs that keep changing what already exists. Adding something new is usually easier than redefining something dozens of other things depend on.
Perform. Data doesn’t just sit there. We write it, find it, query it, share it, report on it and integrate it, and increasingly AI systems retrieve it as context before they act. A model can look beautiful on a diagram and still be terrible to operate. So we design for both how the data is stored and how the data will be used.
And it has to keep performing. It has to perform at scale: when the number of users rises, when the volume of data rises, under real-world conditions and at the peaks, on the busiest day of the year rather than the average one. And it has to keep performing when something unexpected happens.
Support. Grow. Perform. We’ll keep coming back to those three tests throughout this course.
Too Flat, Too Complicated, or Just Wrong
Section titled “Too Flat, Too Complicated, or Just Wrong”I’ve seen data models go wrong in three ways.
The first is choosing the wrong thing to begin with. We use a standard object because it looks close enough, then spend years adding exceptions because it was never the right fit. That’s the square peg.
The second is making the model too flat. Everything goes into one object, and at first that seems wonderfully simple. Then the business grows, and we discover that some of those things have their own lifecycle, can have multiple instances, need their own security, or have relationships of their own. Suddenly we’re representing a one-to-many relationship with Field 1, Field 2 and Field 3, or with increasingly complicated flags and automation. The model didn’t leave us anywhere to grow.
The third is the opposite mistake: we over-normalize. We create an elegant diagram with object after object, every concept perfectly separated. Technically beautiful, practically miserable. Users struggle to understand it, and the page layouts and Lightning pages, with related list after related list, can start to feel endlessly deep. Queries get more complicated, automation crosses more relationships, reporting gets harder, and the platform does more work to answer ordinary business questions.
So which is correct, flat or normalized? There isn’t a formula. You hold a picture of the optimal model in your head and understand the trade-offs as you move away from it. That’s the art of architecture, and we’ll come back to it in module 4 and in the next chapter, where we learn how to model. For now, recognize that the structure itself is an architectural decision.
Be Careful About Changing the Bones
Section titled “Be Careful About Changing the Bones”Once a system is running, I become very cautious about fundamental changes to the data model.
Suppose a text field has existed for years, and someone says, “We don’t really use it that way anymore. Let’s change it to a number.” It sounds like a field change. But what depends on that field? Flows, Apex, reports, integrations, data pipelines, external applications, AI agents. And what happens to the historical data? The platform itself won’t let you change a field’s type while code or flows still reference it, which tells you how far the change reaches.
Sometimes the right answer is not to mutate what already exists. Depending on how severe the change is, I would rather create something new, migrate deliberately, and deprecate the old structure:
Add rather than mutate. Deprecate rather than surprise.
Salesforce even gives you a way to say it in the metadata: a field’s Field Usage can be set to DeprecateCandidate, “planned for deprecation and no longer in use.” That marks the field for everyone who reads the object; it doesn’t hide the field, so retiring it is still a decision you carry out.
Because once other parts of the architecture depend on something, changing its meaning can be much more dangerous than changing its name. The worst version is the field whose name stays the same while its content changes: everything downstream still trusts the name.
Even something as simple as checking the Required box on a field can become a time bomb. If you’ve already collected data, some records won’t have that field populated. Then days, weeks or months later, someone updates one of those records, and the save fails because of the required field, and nobody has that value. A simple change like marking a field required can have unintended and delayed consequences. We’ll come back to Required, and when a value is actually known, in chapter 3.
Beyond the exam: AI builds on the bones too. Ask an AI tool to build an application and it will generate the objects, fields, Flows, Apex, components and tests in minutes. If the original data model was wrong, we haven’t avoided the consequences of a bad decision; we’ve accelerated them, because every generated layer is one more thing depending on that structure. That’s why I want a human architect reviewing an AI-generated data model, understanding it and accountable for it. Module 7 takes this further.
The Bones Come First
Section titled “The Bones Come First”As we go through this course, we’ll talk about a lot of technology: objects and relationships, large data volumes, queries, integration, migration, transactions, security, Data 360 and AI. Underneath all of it is the data model.
If the model supports the business, can grow with the business, and performs for the ways we’re going to use the data, we’ve built a strong foundation. If we get the foundation wrong, everything afterward gets harder.
The data model is the bones. Architects should be very careful when they’re designing the bones. Making changes to existing structures can have cascading consequences.
What an Architect Decides Here
Section titled “What an Architect Decides Here”- Whether the model supports the business, can grow with it, and performs for the ways the data will be used.
- Whether a concept fits a standard object or is a square peg.
- How flat or how normalized to make the model, and why.
- Whether a change to the bones should be an addition, a migration or a deprecation, rather than a change in place.
Explore
Section titled “Explore”- Considerations for Converting the Field Type of a Custom Field (opens in a new tab), Salesforce Help (checked 2026-10-02; re-checked 2026-10-12): which type changes can lose data, and why you can’t change the type of a field that Apex, flows or processes reference.
- Data Classification Metadata Fields (opens in a new tab), Salesforce Help (checked 2026-10-02; re-checked 2026-10-12): Field Usage values (Active, DeprecateCandidate, Hidden), and the other classification fields.